Statistics
Thoughts on Models with Regularization
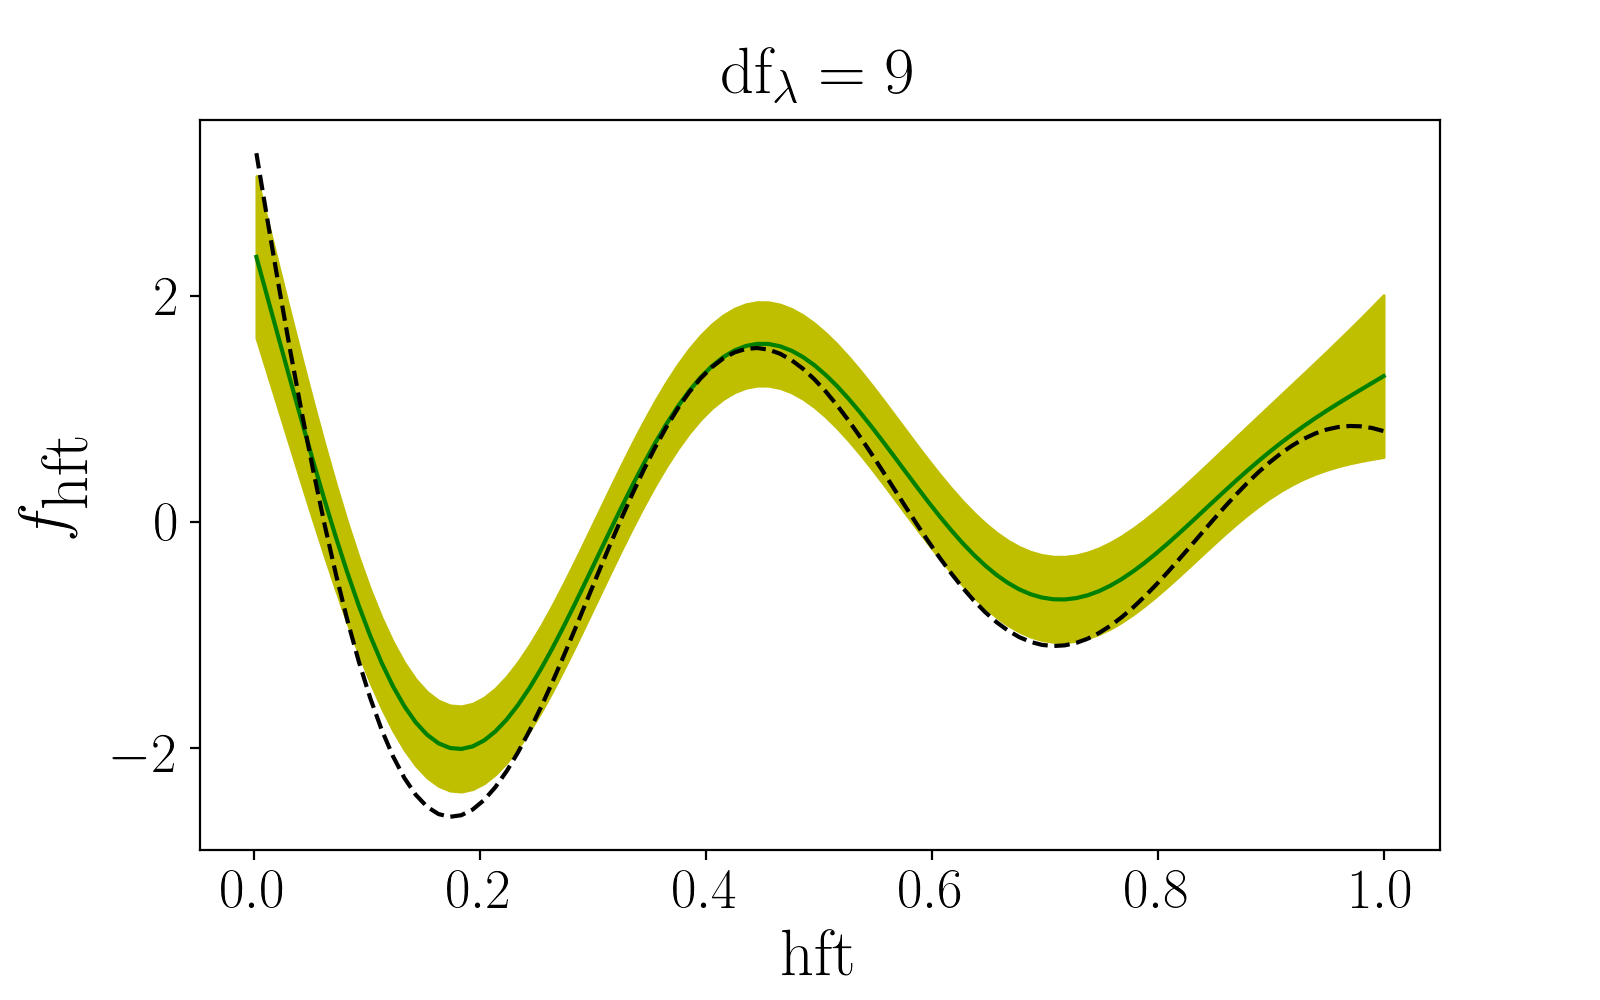
Lately I’ve been reflecting on regularization. Early in my data science career I spent some time working with generalized additive models, but I started focusing more and more on traditional statistical methods. I am re-finding the value in regularization and expect to use more of it going forward.
Edgeworth Series in Python
We often use distributions that can be reasonably approximated as Gaussian, typically due to the Central Limit Theorem. When the sample size is large (and the tails of the distribution are reasonable), the approximation is really good and there’s no point worrying about it. But with modest sample sizes, or if the underlying distribution is heavily skewed, the approximation may not be good enough.
Supervised Learning as Function Approximation
Supervised learning is perhaps the most central idea in Machine Learning. It is equally central to statistics where it is known as regression. Statistics formulates the problem in terms of identifying the distribution from which observations are drawn; Machine Learning in terms of finding a model that fits the data well.
Statistics and Machine Learning: Better Together!
My masters degree focused on Machine Learning, but when I got my first job as a data scientist, I quickly realized there was a lot I still needed to learn about Statistics. Since then I have come to appreciate the nuanced differences between Statistics and Machine Learning and I’m convinced they have a lot to offer one another!
Thoughts on Principal Components Analysis
This is a post with more questions than answers. I’ve been thinking about Principal Components Analysis (PCA) lately.
Three Goals of Statistics: Description, Prediction, and Prescription
The great successes of Machine Learning in recent years are based on our ability to extrapolate and predict based on data. The next big step is learning and leveraging the relationship between cause and effect to prescribe what action to take.
gamdist
Generalized Additive Models in Python